The short answer
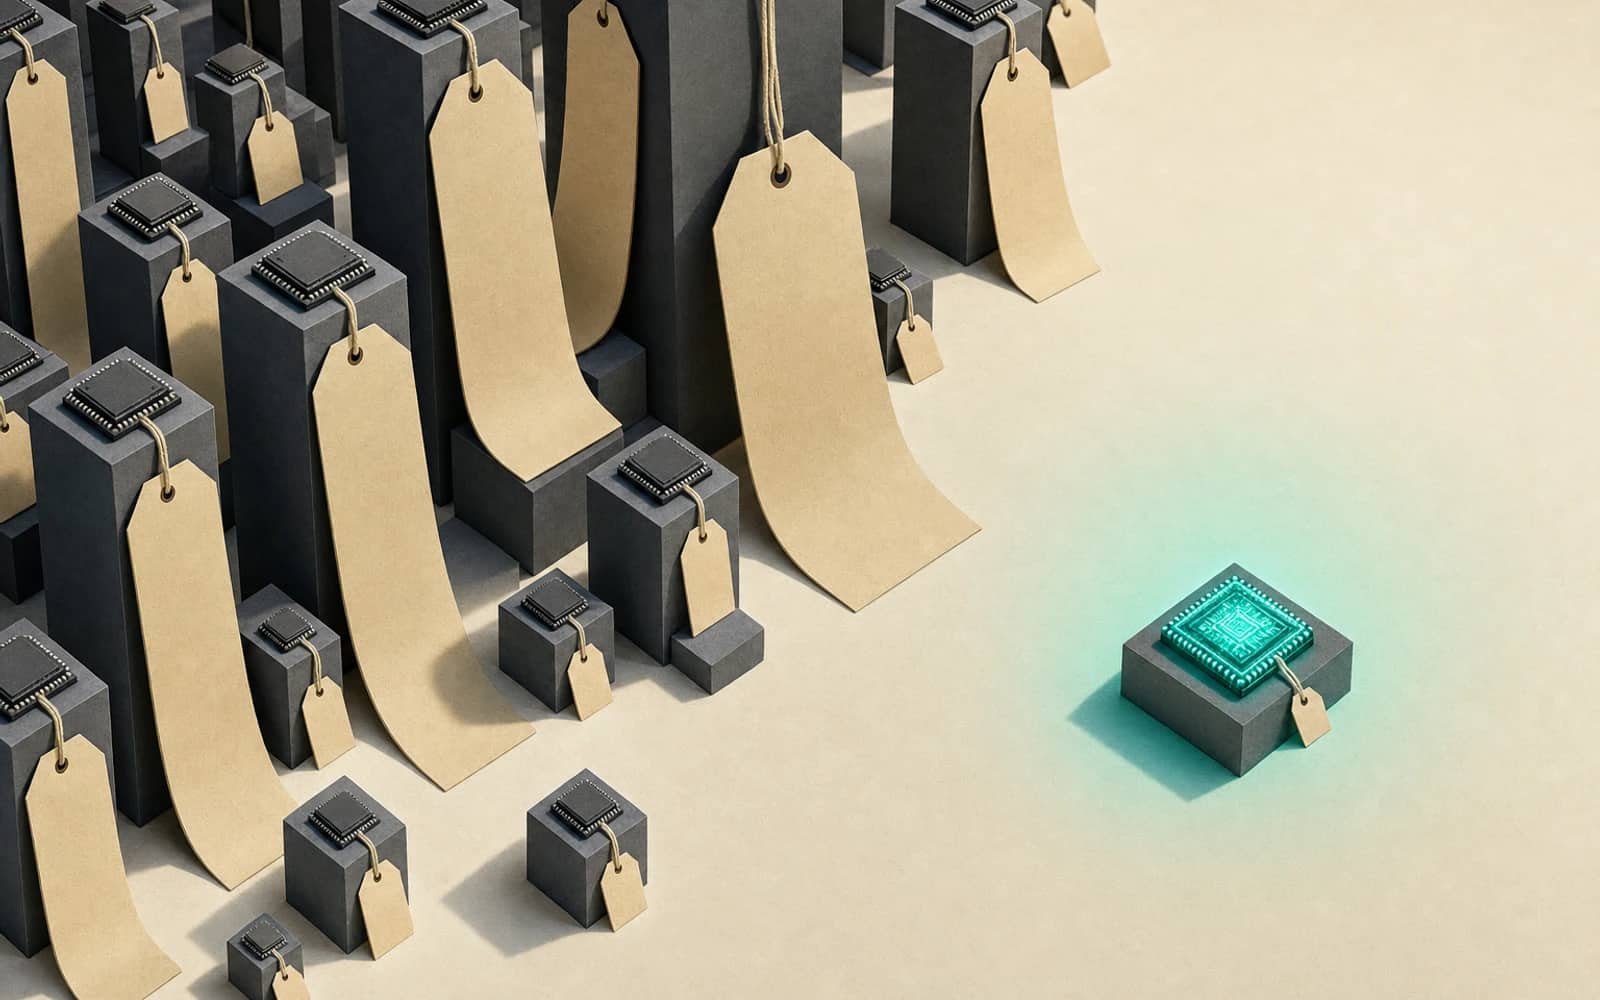
The cheapest way to a top-tier coding score is Codex running GPT-6.1 Sol at xhigh effort: 62.9 on Artificial Analysis's Coding Agent Index for $1.04 a task. The top score, Claude Code with Sonnet 5.5 at max effort, reaches 68.4 but costs $14.19 and 87 minutes a task. That is $1.04 against $14.19 for 5.5 points, so compare models by cost per task, at the effort setting you will actually run.
Key takeaways
- Codex with GPT-6.1 Sol (xhigh) is the cheapest way to a top-tier score. It scores 62.9 on Artificial Analysis's Coding Agent Index for $1.04 a task. The top score, Claude Code with Sonnet 5.5 (max) at 68.4, costs $14.19 a task, about 14 times more for 5.5 points.
- Price per token is not price per task. On the Intelligence Index, GLM-5.3-Flash lists at $0.15 per million input tokens and costs $0.25 a task. GPT-6.1 Sol lists at $2, costs $0.21 at medium effort and scores higher, 47.8 against 41.8.
- The leaderboard score is usually the max-effort score. Claude Code starts Sonnet 5.5 at medium, where it scores 45.9 on coding tasks, not 68.4. At high it scores 55.0 for $1.24 a task, against $14.19 at max for 68.4.
- Running Opus 5.5 at high is by far the best deal for Claude right now. It scores 53.6 on the Intelligence Index at $1.82 per task, which is 93% of the maximum score for only 30% of the maximum cost.
- Claude Code is now the most used AI coding tool at work. 39% of professional developers used it from May to July 2026, up from 18% in January, per JetBrains. GitHub Copilot fell to 21%, Codex rose to 16% and Cursor slipped to 12%.
As of October 1, 2026, the highest-scoring coding agent is Claude Code running Sonnet 5.5 on the "max" reasoning effort level (68.4 score). However, Codex running GPT-6.1 Sol on the "xhigh" reasoning effort level provides the best value for money with a cost of $1.04 per task and a score of 62.9. In other words, you'd need to spend an additional $13 per task to get a 5.5 point higher score (running GPT-6.1 Sol on "xhigh" costs $1 vs running Sonnet 5.5 on "max" costing $14). It's unlikely that most coding teams would get a return from that.
So these AI coding models statistics start with cost per task, and only then get to who uses which tool and how safe the code is. Every figure is dated, and the 200-task budget below is the one to copy into your own spreadsheet.
Will your idea survive the market?
Preuve AI runs 10 agents against live market data and links every claim to a source. Free analysis in 60 seconds.
Which AI coding model gives the most per dollar in 2026?
According to Artificial Analysis, the best value for money of coding agents is Codex running GPT-6.1 Sol on the "xhigh" reasoning effort level. The Coding Agent Index benchmarks AI models inside the program (Claude Code, Codex, etc) that they will run in when you use them to code. It compares models across 303 real-world coding tasks, recording the cost of each attempt (even failed attempts) at list prices. GPT-6.1 Sol, running inside Codex, scores 62.9 at a cost of $1.04 per task. Sonnet 5.5 at xhigh, running inside Claude Code, scores the same but at a cost of $3.33 per task.
The next step up along the best-value line of the chart is Gemini 4 Argon running inside Google's Antigravity CLI at the 'high' reasoning effort level. It scores 63.8 at a cost of $5.84 per task, but it was not yet publicly available, although Artificial Analysis managed to score it in advance. (I've also plotted the two highest-scoring agent pairs: Opus 5.5 at the ‘max’ reasoning effort level, which scores 66.0 at a cost of $13.04 per task, and Sonnet 5.5, which scores 68.4 at a cost of $14.19 per task.) And the lowest: Codex running DeepSeek V4 Flash, which scores 38.7 at a cost of $0.09 per task. I'd guess that the sweet spot for most use cases is in the region of $1 per task. The extra cost of moving from GPT-6.1 Sol to Sonnet 5.5 is $13.15 per task, which means you are paying $2.39 for each extra point of score.

| Agent + model (effort) | Coding Agent Index | Cost per task | Time per task |
|---|---|---|---|
| Codex + DeepSeek V4 Flash 0731 (max) | 38.7 | $0.09 | 18.3 min |
| Codex + GPT-6 Luna (max) | 41.1 | $0.18 | 21.4 min |
| Codex + DeepSeek V4 Pro 0813 (max) | 43.1 | $0.24 | 40.3 min |
| Codex + GPT-6.1 Sol (low) | 57.2 | $0.50 | 8.6 min |
| Codex + GPT-6.1 Sol (medium) | 61.4 | $0.70 | 10.9 min |
| Codex + GPT-6.1 Sol (xhigh) | 62.9 | $1.04 | 15.5 min |
| Claude Code + Sonnet 5.5 (xhigh) | 62.9 | $3.33 | 27.0 min |
| Antigravity CLI + Gemini 4 Argon (high)* | 63.8 | $5.84 | 34.5 min |
| Claude Code + Opus 5.5 (max) | 66.0 | $13.04 | 64.5 min |
| Claude Code + Sonnet 5.5 (max) | 68.4 | $14.19 | 87.4 min |
Source: Artificial Analysis, Coding Agent Index v1.5, read October 1, 2026. Cost per task is the average pay-per-token cost of a single task at list prices (cache pricing applies). Each row on the best-value line is the cheapest pair at that score level. Sonnet 5.5 (xhigh) is included for comparison, even though it is not on the best-value line (Codex running GPT-5.6 Luna at 'max' is, at a score of 43.2 and a cost of $0.44 per task). *Gemini 4 Argon was not yet publicly available, but Artificial Analysis was able to score it in advance.
Three other coding agent / model pairs come within 1.3 points of GPT-6.1 Sol at the 'xhigh' reasoning effort level, but cost between seven and twelve times more per task: Devin running a mixture of Fable 5.1 at the 'xhigh' reasoning effort level and Cognition's SWE-2 model (61.7 at $7.90 per task); Claude Code running Fable 5.1 at the 'max' reasoning effort level (62.2 at $12.39 per task); and Codex running GPT-6 Astra at the 'max' reasoning effort level (61.6 at $7.47 per task).
The score you see is not the setting you use
Every model gets benchmarked, and mostly at max effort, because that is where the best score is. But most of the time, people don't run max. They use xhigh, high or medium thinking. So the number on the leaderboard is often not the number you get.
The reasoning effort level is how long you ask the model to think before answering. The options typically run from 'low' to 'max'. The longer it thinks, the more tokens (a chunk of text that the model reads, writes and is billed for) it will use, so the more the task will cost. Note that if you use Sonnet 5.5 or Opus 5.5 inside Claude Code, they will default to the ‘medium’ reasoning effort level unless you tell them otherwise. Source: Anthropic, documentation for Claude Code.

| Model | Max | Xhigh | High | Medium |
|---|---|---|---|---|
| Claude Opus 5.5 | 57.6, $5.98 | 56.0, $3.46 | 53.6, $1.82 | 51.2, $1.34 |
| Claude Sonnet 5.5 | 56.0, $7.62 | 51.9, $2.74 | 46.7, $1.08 | 40.7, $0.59 |
| Claude Fable 5.1 | 53.4, $7.63 | 53.2, $5.98 | 51.2, $3.91 | 48.9, $2.98 |
| GPT-6 Astra | 52.7, $3.26 | 52.4, $2.31 | 50.9, $1.73 | 49.6, $1.54 |
| GPT-6.1 Sol | 51.8, $0.72 | 51.0, $0.39 | 50.2, $0.32 | 47.8, $0.21 |
Source: Artificial Analysis, Intelligence Index v4.3.2, read October 1, 2026. Each cell contains the index score and the cost per index task at list API prices. I've also plotted GPT-6 Luna (38.1 at $0.068 per task, at 'max') and Grok 4.7 (46.4 at $3.74 per task, at 'xhigh').
Gemini 4 Argon has so far only been tested at 'high' (52.6 at $1.99 per task, 1 point lower than Opus 5.5 at 'high', which scores 53.6 at $1.82 per task). Gemini 4 Argon ranks 3rd on the Coding Agent Index and has the highest score of any of the 31 pairs on the DeepSWE benchmark (78.8).
The gap between reasoning effort levels is even larger for coding agents. For Claude Code running Sonnet 5.5, the score is 68.4 at the 'max' reasoning effort level (at a cost of $14.19 per task, which takes 87 minutes), but only 62.9 at 'xhigh' (at a cost of $3.33 per task, which takes 27 minutes), 55.0 at 'high' (at a cost of $1.24 per task, which takes 12 minutes) and 45.9 at 'medium' (at a cost of $0.62 per task, which takes 8.5 minutes). In other words, the highest-scoring pair on the Coding Agent Index scores 22.5 points lower at its default setting.
On the flip side, Codex with GPT-6.1 Sol does the opposite: its score at medium (61.4) is higher than at max (60.1) while only costing $0.70 vs. $1.55.
More generally, some models lose a lot at lower effort while others don't. For example, from max to medium effort, Sonnet 5.5's Intelligence Index score drops by 15.3 points while the drop for Opus 5.5 is only 6.4, for GPT-6.1 Sol it's 4.0, and for GPT-6 Astra it's 3.1. Compare models at the effort you will really use, not at the one that made the chart.
Sonnet 5.5 is the clearest case for me. On cost, xhigh and max are not worth it compared to high. In Claude Code, max costs about 11 times what high costs and takes about 7 times longer, for 13.4 more points. Each point from xhigh to max adds about $2 per task, against about 26 cents per point from high to xhigh. On the Intelligence Index, max costs about 7 times high, $7.62 against $1.08.
To be clear, in the Coding Agent Index xhigh is 7.9 points better than high, which is a large gain in absolute terms. But Codex with GPT-6.1 Sol at xhigh reaches the same 62.9 for $1.04, about a third of Sonnet's $3.33. So if you need that level, take the cheaper route to it, and if you stay on Sonnet, keep it on high.
One thing I've noticed is that Opus 5.5 seems a lot better at lower settings. According to Artificial Analysis's Coding Agent Index (which only tests it at max), Opus 5.5 at max is expensive, but according to the Intelligence Index (which tests at multiple settings), Opus 5.5 at high (53.6/$1.82) and xhigh (56.0/$3.46) are even more impressive: 93%/97% of the score of Opus 5.5 at max for only 30%/58% of the cost. In fact, at xhigh it scores the same as Sonnet 5.5 at max, but costs less than half as much. If you're using Claude, I think Opus 5.5 at high is a great daily driver, and I recommend bumping up to xhigh for harder tasks, but I wouldn't bother with max (57.6/$5.98) unless you really need that extra 1.6 points.
How are these AI coding numbers measured?
The Coding Agent Index measures coding agents on 3 different test sets, each with equal weight. Specifically, it's the average of DeepSWE v1.1 (by Datacurve; 113 tasks requiring changes to real code), Terminal-Bench 4.0 (by Laude Institute; 66 tasks run from the command line), and SWE-Atlas-QnA (by Scale AI; 124 questions about how a codebase works). Each task is run 3 times and the score is the average percent solved on the first try.
In the sections on effort and open models, I use data from the Artificial Analysis Intelligence Index, which rates models on their own (not as part of a coding agent) across 10 tests, including reasoning, knowledge, and coding. This is not a coding benchmark, but allows me to compare models on their general abilities. I can use it here because it rates 66 models, compared to only 31 agent/model pairs on the Coding Agent Index.
A harness is the wrapper that turns a model into an agent. In this case, it's the coding agent. So, for example, Claude Code, Codex, and Devin are all harnesses. They all affect the score.
All dollar amounts are pay-per-token list prices. Caching reduces that cost significantly; cache hit rates on this board range from 87% for Gemini 3.8 Flash in Google's Antigravity SDK to 99% for DeepSeek in Codex.
Costs are averages. Costs vary significantly between tasks. For example, for Muse Spark 1.3 at xhigh, the median cost per task is $1.68, but the most expensive 5% of tasks cost $11.81 or more (7x the median).
Anthropic launched Opus 5.5 with a 20% reduction in its token price. As of September 22, 2026, the token price for Opus 5.5 is $4 per million input tokens and $20 per million output tokens. There was also a 60% reduction in cache read costs.
Yet in Claude Code at max effort, Opus 5.5 costs $13.04 a task against $10.79 for Opus 5, because it works longer, 64.5 minutes against 41.9. It also scores 6.3 points higher, 66.0 against 59.7, so the extra $2.25 a task buys 6.3 points.
SWE-bench Verified no longer separates out frontier models (they have saturated it), so Vals AI has archived it here. The best model on SWE-bench Verified is Claude Opus 5 (97.0%), with open weights model DeepSeek V4 Pro 0813 at 96.4%. On the Coding Agent Index, the two models are much more separated: Opus 5 at max effort has a score of 59.7, while DeepSeek V4 Pro 0813 has a score of 43.1. I trust the new benchmark more accurately separates out the models (16.6 point difference vs 0.6 point difference in SWE-bench Verified).
Preuve AI runs its own analysis on Claude Opus models. All of the Coding Agent Index and Intelligence Index scores and costs on this page are from one snapshot of the published Artificial Analysis pages, except the Muse Wonder figures, which came out after it. All other numbers on this page are linked. The framing of cost vs ability here is from Slopalytics, which is built on the Artificial Analysis data.
How long does an AI coding agent take per task?
From the Coding Agent Index, the range of time taken by coding agents on an individual task is around 6 minutes to 87 minutes. It's the slower models which score highest. The slowest, and highest-scoring, is Sonnet 5.5 running in Claude Code on the "max" reasoning effort level (87.4 minutes/task, 266 turns/task). The best value for money at the moment is Codex running GPT-6.1 Sol on the "xhigh" reasoning effort level, which takes 15.5 minutes and has 40 turns per task (and scores 62.9). If a person waits on the agent's pull request, those extra 72 minutes are a cost too, even on a flat plan.

| Agent + model (effort) | Coding Agent Index | Minutes per task | Turns per task |
|---|---|---|---|
| Claude Code + Sonnet 5.5 (max) | 68.4 | 87.4 | 266 |
| Claude Code + Opus 5.5 (max) | 66.0 | 64.5 | 155 |
| Antigravity CLI + Gemini 4 Argon (high)* | 63.8 | 34.5 | 149 |
| Codex + GPT-6.1 Sol (xhigh) | 62.9 | 15.5 | 40 |
| Claude Code + Sonnet 5.5 (xhigh) | 62.9 | 27.0 | 78 |
| Claude Code + Fable 5.1 (max) | 62.2 | 34.8 | 37 |
| Codex + GPT-6 Astra (max) | 61.6 | 29.4 | 39 |
| Kimi Code CLI + Kimi K3 | 51.9 | 61.5 | 173 |
Source: Artificial Analysis Coding Agent Index, most recently v1.5, as of October 1, 2026. Minutes per task represents how long the agent took on average to complete a task in the index. Turns per task represents how many steps the agent took on average to complete a task in the index. * not yet publicly available.
Are open-weights and Chinese models catching up?
On a price/point basis, yes, but they are not overtaking the top score yet. “Open weights” means that the lab has released the model publicly in a way that makes it possible for people to run it themselves on their own servers. The best-performing open model in the Intelligence Index is MiMo-V2.6-Pro by Xiaomi, scoring 46.3 at $0.13 per task in the index. It's ~11 points behind Opus 5.5 at the highest effort (max, 57.6 @ $5.98/task), and ~5.5 behind GPT-6.1 Sol at the highest effort (max, 51.8 @ $0.72/task).
The other top-performing Chinese models in the Intelligence Index are also in the low/mid-40s: Qwen3.8 Max (closed) by Alibaba at 45.4 ($5.41/task), GLM-5.3 by Z AI at 44.8, Kimi K3 at 43.6, and Step 5 Preview (closed) by StepFun at 43.7. Meta's closed Muse Spark 1.3 at max, a US reference outside the three frontier labs, scores 48.1 for $1.61.

| Model (effort) | Lab | Open weights | Intelligence Index | Cost per task | Time per task |
|---|---|---|---|---|---|
| MiMo-V2.6-Pro | Xiaomi | Yes | 46.3 | $0.13 | 24.5 min |
| Qwen3.8 Max | Alibaba | No | 45.4 | $5.41 | 36.9 min |
| GLM-5.3 (max) | Z AI | Yes | 44.8 | $2.01 | 14.5 min |
| Kimi K3 (max) | Kimi | Yes | 43.6 | $2.00 | 21.0 min |
| GLM-5.3-Flash (max) | Z AI | Yes | 41.8 | $0.25 | 18.2 min |
| DeepSeek V4.1 Flash (max) | DeepSeek | Yes | 39.5 | $0.27 | 5.3 min |
| Reference: Claude Opus 5.5 (max) | Anthropic | No | 57.6 | $5.98 | 13.8 min |
| Reference: GPT-6.1 Sol (max) | OpenAI | No | 51.8 | $0.72 | 9.9 min |
Source: Artificial Analysis Intelligence Index, most recently v4.3.2, as of October 1, 2026. Cost per task is calculated based on list prices for the models via API. Time per task depends on the provider. DeepSeek V4 Pro 0813 at the highest effort (max) scores 36.0 ($0.67/task).
Inside a coding agent the gap is wider. Running DeepSeek V4 Pro 0813 in Codex gets a score of 43.1 at a cost of $0.24. Running the GLM-5.3 model (in the open source coding agent Opencode) gives a score of 53.6 at a cost of $4.24 per task (48 minutes per task), while Kimi K3 running in Kimi Code CLI gets a score of 51.9 at a cost of $5.05 per task (62 minutes per task). DeepSeek's V4 Flash 0731 has a score of 38.7 at a cost of only $0.09 per task, and is the cheapest on the board (~24 points lower than GPT-6.1 Sol on "xhigh").
GLM-5.3-Flash and DeepSeek V4.1 Flash: cheap tokens, not cheap tasks
These two models have been all the rage in terms of usage recently. DeepSeek V4.1 Flash was the second most-used model on OpenRouter with around 22.7 trillion tokens in the week I measured, and GLM 5.3 Flash was third with around 10.6 trillion tokens. The most-used model in that time period was Space Bunny Alpha (a 'stealth' model from an unnamed lab). Both DeepSeek V4.1 Flash and GLM 5.3 Flash are open weights. DeepSeek released their weights for V4.1 Flash under the MIT license on September 10, 2026. They also provide an API for the model, and offer "off-peak" hours which are 50% of the "peak" hour pricing. One user on r/LocalLLaMA described GLM-5.3-Flash as "a step change in agential capability", though they thought that it wasn't reliable enough to trust at scale.
The pricing of GLM-5.3-Flash and DeepSeek V4.1 Flash is very cheap. GLM-5.3-Flash has list pricing of $0.15 per million input tokens and $0.50 per million output tokens, vs $2 per million input and $10 per million output for GPT-6.1 Sol. However, GLM-5.3-Flash uses a lot more tokens. On average it uses around 68,700 output tokens per task, which works out at $0.25 per task. The model also takes an average of 18 minutes to complete each task. DeepSeek V4.1 Flash is similar, using around 88,600 output tokens at a cost of $0.27. This is very fast though, as the model can output 209 tokens per second, and each task only takes an average of around 5 minutes. GPT-6.1 Sol at the medium reasoning effort level uses around 8,100 output tokens per task at a cost of $0.21 and scores 47.8.
| Model (effort) | List price, $ per M tokens in / out | Intelligence Index | Output tokens per task | Time per task | Cost per task |
|---|---|---|---|---|---|
| GLM-5.3-Flash (max) | $0.15 / $0.50 | 41.8 | 68,673 | 1,091 s | $0.25 |
| DeepSeek V4.1 Flash (max) | $0.30 / $1.20 | 39.5 | 88,574 | 319 s | $0.27 |
| DeepSeek V4.1 Flash (non-reasoning) | $0.30 / $1.20 | 24.7 | 33,699 | 173 s | $0.15 |
| GPT-6.1 Sol (medium) | $2 / $10 | 47.8 | 8,070 | 138 s | $0.21 |
| GPT-6.1 Sol (high) | $2 / $10 | 50.2 | 13,192 | 218 s | $0.32 |
| GPT-6 Luna (max) | $0.10 / $0.50 | 38.1 | 49,956 | 398 s | $0.068 |
Source: Individual model pages in the Intelligence Index, most recently at v4.3.2, as of October 1, 2026. DeepSeek lists its pricing at its “peak” price; “off-peak” hours are half that. Time per task depends on the provider.
It’s worth noting that these models can be run on your own server or a rented GPU server, which may help with concerns about not wanting to send code to a third-party. However, at current list prices through paid API services, GPT-6.1 Sol at the medium effort is cheaper per task and scores higher than both of these models. GPT-6.1 Sol at the lowest effort is even cheaper ($0.13/task) and scores 42.1.
Which AI model is best for front-end work?
There's something notable about Anthropic's models, Opus and Fable above all: taste, and front-end skills in particular. On that, they're far ahead of every other lab, US, Chinese, all of them. Months and months ahead, if you ask me.
Arena's WebDev board, where people vote on which of two AI-built web apps they prefer, backs that for Opus. On September 30, 2026, with 830,738 votes across 137 models, Claude Opus 5.5 at max ranked first at 1818, 29 points ahead of GPT-6 Astra. Fable 5.1 ranked fourth at 1751, behind two OpenAI models. The best Chinese model, Qwen3.8 Max, ranked ninth at 1671.
There are some things worth noting: The benchmark snapshot above was taken before Meta released Muse Wonder Full on October 12th. Their model scores 68 on the Coding Agent Index and is available in Muse Code. It scores on par with Claude Code running Sonnet 5.5 at max but initial reviews indicate the model is not as strong in front-end design and 3D, even though it is strong in backend work. I do not know the cost of using Muse Wonder Full per token and it is only available through a Muse Code subscription. However, Meta is also selling Muse Wonder on their API (priced at $4 per 1M input tokens and $20 per 1M output tokens), and in Muse Code it scores a 63 for $8.05 per task, which scores on par with Codex GPT-6.1 Sol running at xhigh for $1.04 per task. For Meta's consumer assistant, see my Meta Muse review.
Skip weeks of manual research
Get complete market research, sourced proof, competitor map, and pricing data for your idea instantly.
How do you pick a coding model by cost per task?
To estimate the cost to use different AI coding agents, you need to multiply the cost per task by how many tasks you have per month. To get the cost per solved task, you need to divide the cost per task by the index as a share.
| Agent + model (effort) | Index | 200 tasks a month | Rough cost per solved task | Agent hours a month |
|---|---|---|---|---|
| Claude Code + Sonnet 5.5 (max) | 68.4 | $2,838 | $20.75 | 291 |
| Claude Code + Opus 5.5 (max) | 66.0 | $2,608 | $19.76 | 215 |
| Claude Code + Sonnet 5.5 (xhigh) | 62.9 | $666 | $5.29 | 90 |
| Codex + GPT-6.1 Sol (xhigh) | 62.9 | $208 | $1.65 | 52 |
| Codex + GPT-6.1 Sol (medium) | 61.4 | $140 | $1.14 | 36 |
| Codex + DeepSeek V4 Flash 0731 (max) | 38.7 | $18 | $0.23 | 61 |
Sources: My calculations using the Artificial Analysis Coding Agent Index v1.5 as of October 1, 2026. To get the estimated cost per month, I multiplied the cost per task by 200 (the assumed tasks per month). To get the agent hours per month, I multiplied the minutes per task by 200 and then divided by 60. To get the cost per solved task, I divided the cost per task by the index divided by 100. Note that this is approximate as the index is an average of three different test sets.
If I had 200 tasks per month, I would do 150 of them on GPT-6.1 Sol at medium and 50 of the hardest on Claude Code with Sonnet 5.5 at max, for an estimated cost of $105 + $710 (at average) = $815 per month. This compares to $2,838 if I did them all at the top setting. The cost on the hardest tasks would likely be above average. At the max setting on Sonnet 5.5, about 1 in 20 tasks costs $28.29 or more.
Note that if you are using a flat rate monthly plan, you will need to consider how many of the tasks will use up your limit. Also, if you are waiting for each of the tasks to complete, you will need to consider how many hours of work you will be waiting for. At the top setting, the agents take about 291 hours per month to complete the 200 tasks, compared to 52 hours if you use GPT-6.1 Sol at xhigh. If you are a non-coder looking to use an AI to build an application, see my comparison of the AI app builders which have flat rate plans.
How many developers use AI coding tools in 2026?
Almost all professional developers are using AI coding tools, and most of them are using them on a daily basis. According to the JetBrains Developer Ecosystem Survey 2026, in a survey of over 15,000 professional developers conducted between May and July 2026, 90% of respondents used an AI coding agent at work at least weekly, and 68% used them at work daily. Claude Code doubled to 39% adoption at work, up from 18% in January, and 47% in the United States. GitHub Copilot, which was the most popular a year ago, dropped to 21% of developers.
When using the default medium setting, Claude Code with Sonnet 5.5 gets an index score of 45.9 at $0.62 per task compared to Codex with GPT-6.1 Sol at medium with an index score of 61.4 at $0.70 per task.
Most interestingly, Codex seems to have increased its adoption by a factor of 5, up from 3% in the January survey to 16% in this one, while Cursor seems to have dropped from 18% to 12%. In their second post discussing the survey results, they also discuss how much of the code developers have worked on in the last month was fully written by AI coding agents, which on average is about 47%. The full Stack Overflow Developer Survey 2026 was not out yet when I gathered these numbers, but in the meantime they did a lookback on the usage of AI tools by developers, which went from 44% in 2023 to 79% in 2025 and the usage of agents specifically went from 31% in the 2025 survey to 59% in a pulse survey they ran in April 2026.
| Signal | Number | Source |
|---|---|---|
| Professional developers using AI coding agents at work | 90% at least weekly, 68% daily | JetBrains, May to July 2026 |
| Claude Code used at work | 39% (18% in January 2026; 47% in the US) | JetBrains, May to July 2026 |
| GitHub Copilot used at work | 21% (29% a year earlier) | JetBrains, May to July 2026 |
| Codex and Cursor used at work | Codex 16% (3% in January); Cursor 12% (18% in January) | JetBrains, May to July 2026 |
| Share of code fully written by agents, self-reported average | About 47% | JetBrains, May to July 2026 |
| Developers using AI agents | 31% (2025 survey); 59% (April 2026 pulse) | Stack Overflow, September 30, 2026 |
Sources: JetBrains Developer Ecosystem Survey 2026 which surveyed over 15,000 professional developers, two blog posts in August 2026 and the Stack Overflow blog, all read on October 1, 2026. Adoption counts regular use at work, so one developer can count toward several tools.
How big is the AI coding tools market in 2026?
A little over $9 billion in 2026, according to Mordor Intelligence ($9.35 billion) and they are predicting it to grow to $29.96 billion by 2031. Another source, The Business Research Company has it at $9.45 billion. Just to give a perspective for these numbers, below are the run rates of the companies in this space, which are annualized revenues calculated for the current month. As such, the numbers are not for a calendar year.
Cursor had about $2.6 billion in annualized business revenue in early June 2026, per company data shared with Reuters, when SpaceX agreed to buy its maker, Anysphere, for $60 billion in stock. Anthropic's last own figure for Claude Code was over $2.5 billion in run-rate revenue in its February 12, 2026 funding announcement. On Microsoft's July 29, 2026 earnings call, Satya Nadella said GitHub Copilot had 50 million users, that Copilot revenue grew more than 60% on the previous quarter after usage-based billing started, and that one in three pull requests on GitHub now involves an agent.
| Signal | Number | Source |
|---|---|---|
| AI code tools market, 2026 | $9.35B, to $29.96B by 2031 (26.23% a year) | Mordor Intelligence |
| AI code tools market, 2026 (second estimate) | $9.45B, to $22.06B by 2030 (23.6% a year) | The Business Research Company, September 2026 |
| Cursor annualized business revenue | About $2.6B (early June 2026) | Reuters, June 16, 2026 |
| Cursor maker Anysphere, SpaceX all-stock deal | $60B | Reuters, June 16, 2026 |
| Claude Code run-rate revenue | Over $2.5B (February 12, 2026) | Anthropic |
| GitHub Copilot users | 50 million; revenue up 60%+ on the prior quarter | Microsoft earnings call, July 29, 2026 |
Sources: The market size is from Mordor Intelligence and The Business Research Company report pages, all read on October 1, 2026. The company run rate revenue is from Reuters reporting on data shared by Cursor, Anthropic's February 12, 2026 funding announcement and Microsoft's July 29, 2026 earnings call. The company run rate revenue is based on the revenue for the month times twelve and not for a calendar year.
Do AI coding tools make developers faster?
Probably, but the best study can no longer measure by how much. METR's randomized trials assign each task to "AI allowed" or "AI not allowed" and time both. Its early-2025 study found tasks took 19% longer with AI. In the follow-up, started in August 2025, returning developers finished an estimated 18% faster with AI and new recruits 4% faster, both with wide margins of error.
METR itself wrote that the signal for this second study is not reliable, with 30-50% of the developers not submitting some tasks because they didn't want to work on them without AI and some refusing outright to participate in the study. I think this is the most valuable adoption number on the entire page. When developers would rather skip a task than do it without AI, a clean with-and-without comparison stops being possible. METR says it believes developers are more sped up in early 2026 than in early 2025, and is changing its study design.
Is AI-generated code secure?
Not really and it didn't improve much with model upgrades. In their GenAI Code Security Report 2026 published on July 28, 2026, Veracode tested over 100 models in 4 snapshots over time and they found that the models have an average security pass rate of 56%, compared to 55% in the first report they published. This means that for about 44% of the tasks the models produce code with known vulnerabilities, even though the code almost always compiles.
GPT-5.5 is at the top of their leaderboard from the summer with a score of 68%, but most of the models they tested have a score between 50-53%. Code-specific models are not better than the general ones (51% vs 52%), while the reasoning models score a little better (56% vs 51%). In a follow-up article published on August 27, they tested GPT-5.6 Sol which scores 70% overall and 85% for Python tasks (vs 70% for GPT-5.5). Unfortunately, the tables above don't include the security score of the models, so you'll have to add the cost of reviewing the code that the models produce to the cost shown in the tables.
Every model, sorted by Intelligence Index
All 110 effort settings of the 66 models from 26 labs available on Artificial Analysis. To keep things simple, I’ve only included each model at its best-scoring setting. Models with open weights are marked. Many Chinese labs have models on the list, including Alibaba, DeepSeek, Kimi, MiniMax, StepFun, Tencent, Xiaomi, and Z AI. The raw data behind every table on this page, all 110 settings and all 31 agent pairs, is in the research file for this post.
Show all 66 models (Artificial Analysis)
| Model (effort) | Lab | Open weights | Intelligence Index | Cost per task | Time per task | Price $ per M tokens in / out |
|---|---|---|---|---|---|---|
| Claude Opus 5.5 (max) | Anthropic | 57.6 | $5.98 | 828 s | $4 / $20 | |
| Claude Sonnet 5.5 (max) | Anthropic | 56 | $7.62 | 867 s | $2 / $10 | |
| Claude Fable 5.1 (max) | Anthropic | 53.4 | $7.63 | 715 s | $10 / $50 | |
| GPT-6 Astra (max) | OpenAI | 52.7 | $3.26 | 528 s | $10 / $50 | |
| Gemini 4 Argon (high) | 52.6 | $1.99 | not measured | $2 / $10 | ||
| GPT-6.1 Sol (max) | OpenAI | 51.8 | $0.72 | 593 s | $2 / $10 | |
| Muse Spark 1.3 (max) | Meta | 48.1 | $1.61 | 351 s | $1.25 / $4.25 | |
| GPT-6 Sol (max) | OpenAI | 47.6 | $1.04 | 414 s | $2 / $10 | |
| Grok 4.7 (xhigh) | SpaceXAI | 46.4 | $3.74 | 1158 s | $2 / $6 | |
| MiMo-V2.6-Pro | Xiaomi | Yes | 46.3 | $0.13 | 1471 s | $0.435 / $0.87 |
| Qwen3.8 Max (0902) | Alibaba | 45.4 | $5.41 | 2214 s | $2 / $6 | |
| GLM-5.3 (max) | Z AI | Yes | 44.8 | $2.01 | 870 s | $1.4 / $4.4 |
| Step 5 Preview | StepFun | 43.7 | $0.72 | 683 s | $1 / $2.7 | |
| Kimi K3 (max) | Kimi | Yes | 43.6 | $2.00 | 1258 s | $3 / $15 |
| GPT-5.6 Terra (max) | OpenAI | 42.1 | $1.40 | 425 s | $2 / $12 | |
| GLM 5.3 Flash (max) | Z AI | Yes | 41.8 | $0.25 | 1091 s | $0.15 / $0.5 |
| Gemini 3.8 Flash (high) | 40.9 | $1.24 | 311 s | $0.75 / $3.75 | ||
| Qwen3.8 2.4T A95B | Alibaba | Yes | 39.9 | $2.16 | 1391 s | $2 / $6 |
| Qwen3.8-Flash-Next | Alibaba | Yes | 39.8 | $0.37 | 1539 s | $0.15 / $0.47 |
| DeepSeek V4.1 Flash (max) | DeepSeek | Yes | 39.5 | $0.27 | 319 s | $0.3 / $1.2 |
| GPT-6 Luna (max) | OpenAI | 38.1 | $0.068 | 398 s | $0.1 / $0.5 | |
| MiMo-V2.6-Flash | Xiaomi | Yes | 37.9 | $0.062 | 1411 s | $0.14 / $0.28 |
| DeepSeek V4 Pro 0813 (max) | DeepSeek | Yes | 36 | $0.67 | 512 s | $1.32 / $3.96 |
| DeepSeek V4 Flash Vision (max) | DeepSeek | 34.8 | $0.31 | 242 s | $0.44 / $1.32 | |
| Qwen3.8 27B (xhigh) | Alibaba | Yes | 33.7 | $1.01 | 1237 s | $0.5 / $3 |
| Gemini 3.1 Pro Preview | 29.7 | $0.68 | 161 s | $2 / $12 | ||
| MiniMax-M3 | MiniMax | Yes | 29.2 | $0.51 | 509 s | $0.3 / $1.2 |
| Quasar 438B (max) | Multiverse Computing | 26.7 | $2.02 | 508 s | $0.6 / $1.8 | |
| Apodex 1.1 | Apodex | 26.4 | $0.46 | not measured | $0.3 / $3 | |
| GPT-5.5 Instant (June 2026) | OpenAI | 26 | $0.69 | 45 s | $5 / $30 | |
| Kimi K2.7 Code | Kimi | Yes | 25.8 | $0.54 | 352 s | $0.95 / $4 |
| Inkling Small | Thinking Machines | Yes | 25.7 | $0.089 | 142 s | $0.3 / $1.2 |
| Hy3 | Tencent | Yes | 25.3 | $0.072 | 509 s | $0.136 / $0.555 |
| Qwen3.7 Plus | Alibaba | 25.2 | $0.22 | 616 s | $0.4 / $1.6 | |
| Solar Mini 4 | Upstage | 24.1 | $0.36 | 430 s | $0.1 / $0.4 | |
| Nemotron 3 Ultra 550B A55B | NVIDIA | Yes | 22.9 | $0.60 | 173 s | $0.6 / $2.5 |
| Gemini 3.5 Flash-Lite (high) | 22.2 | $0.12 | 55 s | $0.3 / $2.5 | ||
| LongCat 2.0 | LongCat | Yes | 19.1 | $0.059 | not measured | $0.3 / $1.2 |
| Qwen3.5 397B A17B | Alibaba | Yes | 18.4 | $0.47 | 195 s | $0.6 / $3.6 |
| Qwen3.6 35B A3B | Alibaba | Yes | 18.2 | $0.47 | 268 s | $0.375 / $2.25 |
| Muse Glimmer (high) | Meta | Yes | 17.5 | $0.057 | 97 s | $0.325 / $1.35 |
| Claude 4.5 Haiku | Anthropic | 16.9 | $0.28 | 150 s | $1 / $5 | |
| Ring-2.6-1T (xhigh) | InclusionAI | Yes | 16.6 | $0.29 | 342 s | $0.3 / $2.5 |
| Qwen3.5 122B A10B | Alibaba | Yes | 15.6 | $0.33 | 133 s | $0.4 / $3.2 |
| Gemma 4 31B | Yes | 14.7 | no list price | 347 s | no list price | |
| Mistral Medium 3.5 (high) | Mistral | Yes | 14.2 | $0.50 | 150 s | $1.5 / $7.5 |
| Command A+ | Cohere | Yes | 13.1 | no list price | 105 s | no list price |
| Nemotron 3.5 Lightning | NVIDIA | Yes | 12.9 | $0.093 | 116 s | $0.06 / $0.2 |
| Nemotron 3 Super 120B A12B | NVIDIA | Yes | 12.8 | $1.64 | 647 s | $0.3 / $0.9 |
| Mercury 2.5 | Inception | 12.3 | $0.12 | 14 s | $0.25 / $0.75 | |
| gpt-oss-120b (high) | OpenAI | Yes | 11.6 | $0.11 | 144 s | $0.15 / $0.595 |
| Mistral Small 4 | Mistral | Yes | 11.3 | $0.015 | 97 s | $0.15 / $0.6 |
| Qwen3.5 9B | Alibaba | Yes | 11.2 | $0.21 | 788 s | $0.135 / $0.2 |
| Granite 4.2 8B | IBM | Yes | 11.1 | $0.024 | 490 s | $0.06 / $0.25 |
| Ling 3.0 Tiny | InclusionAI | Yes | 11.1 | no list price | 1221 s | no list price |
| Trinity Large Thinking | Arcee AI | Yes | 10.8 | $0.12 | 128 s | $0.25 / $0.8 |
| North Mini Code | Cohere | Yes | 9.9 | no list price | 236 s | no list price |
| Mistral Large 3 (non-reasoning) | Mistral | Yes | 9.3 | $0.031 | 70 s | $0.5 / $1.5 |
| Qwen3 Coder Next (non-reasoning) | Alibaba | Yes | 9.2 | $0.55 | 198 s | $0.35 / $1.2 |
| Granite 4.2 3B | IBM | Yes | 9.1 | $0.006 | 80 s | $0.03 / $0.12 |
| gpt-oss-20b (high) | OpenAI | Yes | 9 | $0.012 | 98 s | $0.07 / $0.18 |
| NVIDIA Nemotron 3 Nano 30B A3B | NVIDIA | Yes | 8.9 | $0.017 | 133 s | $0.05 / $0.2 |
| Celeris-1 (non-reasoning) | Celeris | 6.3 | $0.050 | 3 s | $0.2 / $0.7 | |
| Ministral 3 14B (non-reasoning) | Mistral | Yes | 6 | $0.019 | 81 s | $0.2 / $0.2 |
| Ministral 3 8B (non-reasoning) | Mistral | Yes | 5.5 | $0.011 | 80 s | $0.15 / $0.15 |
| Ministral 3 3B (non-reasoning) | Mistral | Yes | 4.8 | $0.008 | 63 s | $0.1 / $0.1 |
Source: Artificial Analysis Intelligence Index v4.3.2, read October 1, 2026. One row per model at its highest-scoring effort setting; cost per index task at list API prices; time per task in seconds, measured on one API provider.
What I would do with these numbers
Pick the cheapest pair that clears the score your work needs, and send only the hardest tasks to max. On these numbers that means GPT-6.1 Sol in Codex for most teams, Opus 5.5 or Sonnet 5.5 at high if you live in Claude Code, Sonnet 5.5 at max only for the hardest tasks, and an open-weights model when the code cannot leave your own servers. To find your score, run 20 of your own tasks through two or three pairs and count accepted results, retries and review time next to the bill. The same logic applies if you build a product on top of these models: your margin is set by cost per task, which is why I wrote about whether AI wrapper startups are worth building.
None of these benchmarks test whether anyone wants what you are building. I built Preuve for that question: you can run your idea through a validation scan of 60+ live data sources for demand and competitors before an agent spends its first task on it. The first idea score is free.
Methodology and sources
| Source | What we used | Size or date | Limitation |
|---|---|---|---|
| Artificial Analysis, Coding Agent Index v1.5 | Score, cost per task (mean, median, 95th percentile), wall time, turns, tokens and cache hit rate for every agent and model pair | 31 agent and model pairs (one not yet publicly available), 303 tasks each run 3 times, read October 1, 2026 | Pay-per-token list prices, not subscription costs; each pair is tested in one harness and at the effort levels Artificial Analysis chose |
| Artificial Analysis, Intelligence Index v4.3.2 and model pages | Index score, cost per task, time per task, output tokens per task and list prices per reasoning effort level | 110 model and effort settings (66 models, 26 labs), read October 1, 2026 | A general index of 10 tests, not coding alone; time per task depends on the API provider Artificial Analysis measured |
| Slopalytics | The framing: cost and time per task against intelligence, per effort level | Viewer over Artificial Analysis data, read October 1, 2026 | Not a data source in its own right; every figure here comes from Artificial Analysis |
| OpenRouter, LLM rankings | Weekly token volume rank of DeepSeek V4.1 Flash and GLM 5.3 Flash | Top 10 models by weekly tokens, read October 1, 2026 | One API marketplace, not the whole market; it favors cheap models used in bulk |
| r/LocalLLaMA, "GLM-5.3-Flash is 100% a step change in agential capability" | One user view of GLM-5.3-Flash for agent work | One thread, August 30, 2026 | A single self-selected user, not a measurement |
| JetBrains, "AI Coding Agents: Adoption Trends" | Tool adoption at work, weekly and daily agent use | Developer Ecosystem Survey 2026, 15,000+ professional developers, May to July 2026 | Self-reported; reweighted by JetBrains, which also sells AI coding tools |
| JetBrains, "How Much Code Do Developers Really Let Agents Write?" | Share of code fully written by agents, self-reported average | Developer Ecosystem Survey 2026, May to July 2026 | Self-reported estimate of last month, not measured from code |
| Stack Overflow, "Getting ready for 2026 results: A look back on Developer Survey findings" | AI tool use 2023 to 2025 and agent use in the April 2026 pulse survey | Post of September 30, 2026; 2025 survey plus an April 2026 pulse | The full 2026 survey results were not yet published on October 1, 2026 |
| Microsoft fiscal 2026 fourth-quarter earnings call (transcript, The Motley Fool) | GitHub Copilot users, Copilot revenue growth, share of pull requests involving an agent | Call of July 29, 2026; 50 million figure also reported by CNBC the same day | Company statements; "users" is not defined as paid seats |
| CNBC, "Microsoft Q4 earnings report 2026" | Second source for the 50 million GitHub Copilot users | Article of July 29, 2026 | Repeats the company figure |
| Reuters, "SpaceX locks in $60 billion Cursor deal to close gap with rivals in AI coding race" | Cursor's annualized business revenue and the acquisition value | Article of June 16, 2026, company data from early June | Annualized revenue is a run rate, not audited yearly revenue |
| Anthropic, Series G announcement | Claude Code run-rate revenue | Post of February 12, 2026 | Anthropic's latest own Claude Code revenue figure; later numbers are third-party estimates |
| Anthropic, Claude Opus 5.5 page | Opus 5.5 token prices and cache read price against Opus 5 | Page of September 22, 2026, read October 1, 2026 | List prices; subscription plans count usage differently |
| Anthropic, Claude Code documentation, "Model configuration" | Default effort level for Opus 5.5 and Sonnet 5.5 in Claude Code | Documentation page read October 1, 2026 | Defaults change between releases; an organization can set its own default |
| DeepSeek, V4.1 Flash release and Hugging Face model card | Release date, peak and off-peak pricing, open weights under the MIT license | Release of September 10, 2026 | Vendor page; off-peak rates apply only at set hours |
| METR, "We are Changing our Developer Productivity Experiment Design" | Speed-up estimates from its randomized developer studies | Post of February 24, 2026; 57 developers in the second study | METR itself calls the second study an unreliable signal because of who dropped out |
| Veracode, 2026 GenAI Code Security Report | Security pass rate, best model, coding-specialized vs general models, reasoning vs non-reasoning | 100+ models over four testing snapshots, report of July 28, 2026 | Controlled single-task tests, not production code; vendor sells code scanning |
| Veracode, "GPT-5.6 Sol Shows Why a Better Model Isn't a Uniformly Safer Model" | GPT-5.6 Sol secure-code result | Post of August 27, 2026 | One model, same test set |
| Mordor Intelligence, AI code tools market | 2026 market size and 2031 forecast | Report page read October 1, 2026 | Paid report; market definitions vary between firms |
| The Business Research Company, AI code tools global market report | Second 2026 market size estimate | Report page of September 16, 2026 | Paid report; market definitions vary between firms |
| Arena, Code Arena WebDev leaderboard | Front-end web development ranks of Opus 5.5, GPT-6 Astra, Fable 5.1 and Qwen3.8 Max | 830,738 votes across 137 models, board dated September 30, 2026 | Human preference votes between two generated apps, not a pass or fail test |
| Vals AI, SWE-bench Verified board | Archived status and top scores | Board read October 1, 2026 | Archived: new models are no longer tested on it |
| Artificial Analysis, "Muse Wonder and Muse Wonder Full" | Coding Agent Index scores, token prices and availability of Muse Wonder and Muse Wonder Full | Article of October 12, 2026, read October 16, 2026 | Released after the October 1 snapshot, so neither model is in the tables; Muse Wonder Full has no per-token price, so no cost per task |
| Artificial Analysis, Codex vs Muse Code comparison | Coding Agent Index cost per task of Muse Code with Muse Wonder | Comparison page read October 16, 2026 | Not part of the October 1 snapshot behind the tables |
| How I AI (Claire Vo), "Meta's new 'Muse Wonder' model: good for AI agents, bad for design" | Early hands-on view of Muse Wonder and Wonder Full on backend and front-end tasks | Episode of October 14, 2026; nearly 20 tasks | One tester, a first look rather than a benchmark |
| r/singularity, "BridgeMind On Muse Wonder" | Early user reports of weak 3D output | One thread, October 2026 | Self-selected users and one-off demos, not a measurement |
FAQ
Which AI coding model gives the best value in 2026?
Codex running GPT-6.1 Sol at xhigh effort scored 62.9 on Artificial Analysis's Coding Agent Index for $1.04 per task, the best score per dollar near the top of the board. At medium effort the same pair scored 61.4 for $0.70. The highest score, Claude Code with Sonnet 5.5 at max effort, reached 68.4 for $14.19 per task. Costs are pay-per-token list prices measured on 303 real coding tasks.
How much does an AI coding agent cost per task?
Between $0.09 and $14.19 per task on Artificial Analysis's Coding Agent Index. DeepSeek V4 Flash in Codex costs $0.09 for a 38.7 score; GPT-6.1 Sol in Codex costs $0.50 to $1.55 depending on effort; Claude Code with Opus 5.5 or Sonnet 5.5 at max costs $13 to $14. The averages hide spread: for Sonnet 5.5 at max, the median task costs $12.35 and the most expensive 5% cost $28.29 or more.
Are cheap Chinese models like GLM-5.3-Flash and DeepSeek V4.1 Flash worth it for coding?
Their token prices are low, but per task they are not cheap. On Artificial Analysis's Intelligence Index, GLM-5.3-Flash scores 41.8 for $0.25 per task and DeepSeek V4.1 Flash scores 39.5 for $0.27, because both write roughly 70,000 to 90,000 output tokens per task. GPT-6.1 Sol at medium effort scores 47.8 for $0.21. Both Flash models are open weights, so you can run them on your own servers, which removes the list price and keeps code in-house. They ranked 2nd and 3rd on OpenRouter by weekly tokens used.
Is the leaderboard score what I get at my reasoning effort setting?
Often not. Reasoning effort is how long a model thinks before it answers, and leaderboards mostly report max. On Artificial Analysis's Coding Agent Index, Claude Code with Sonnet 5.5 scores 68.4 at max for $14.19 a task, 62.9 at xhigh for $3.33, 55.0 at high for $1.24 and 45.9 at medium for $0.62, and Claude Code starts Sonnet 5.5 at medium. Codex with GPT-6.1 Sol scores 61.4 at medium and 60.1 at max. For Sonnet 5.5, high is the cost-sensible default; if you need the 62.9 level, GPT-6.1 Sol at xhigh reaches it for $1.04.
Which AI coding tool do most developers use in 2026?
Claude Code. JetBrains' Developer Ecosystem Survey 2026 (15,000+ professional developers, May to July 2026) found 39% use Claude Code at work, up from 18% in January 2026, and 47% in the United States. GitHub Copilot is at 21%, down from 29% a year earlier, Codex at 16% and Cursor at 12%. 90% of professional developers use an AI coding agent at least weekly.
Is AI-generated code secure in 2026?
Not by default. Veracode's 2026 GenAI Code Security Report (July 28, 2026) found an average security pass rate of 56% across more than 100 models, barely up from 55% in its first report, so about 44% of coding tasks introduced a known vulnerability. GPT-5.5 led its summer leaderboard at 68%, and GPT-5.6 Sol reached 70% in an August extension test. Review and scan AI-written code before release.
Cite this page
Last updated October 16, 2026
Forat, V. (2026, October 16). AI Coding Models Statistics 2026: The Real Cost per Task. Preuve AI. https://preuve.ai/blog/ai-coding-models-statistics-2026
Forat, Vincent. “AI Coding Models Statistics 2026: The Real Cost per Task.” Preuve AI, 16 Oct. 2026, preuve.ai/blog/ai-coding-models-statistics-2026.
Forat, Vincent. “AI Coding Models Statistics 2026: The Real Cost per Task.” Preuve AI. October 16, 2026. https://preuve.ai/blog/ai-coding-models-statistics-2026.
@misc{forat2026-ai-coding-models-statistics-2026,
  author = {Forat, Vincent},
  title = {{AI Coding Models Statistics 2026: The Real Cost per Task}},
  howpublished = {Preuve AI},
  year = {2026},
  month = oct,
  url = {https://preuve.ai/blog/ai-coding-models-statistics-2026},
  note = {Last updated October 16, 2026}
}
Vincent
5 years in B2B growth, building Preuve AI in public. 82% of ideas it scores aren't ready, the point is finding out in 10 minutes, not 3 months.
Follow on X →
Building is expensive. Validation is free.
Run your idea through 10 AI agents before you write a line of code. Every claim source-linked.